Hevo
Move data into a warehouse and manage ingestion with built-in transformations
Build Python data pipelines and run them on managed dltHub infrastructure
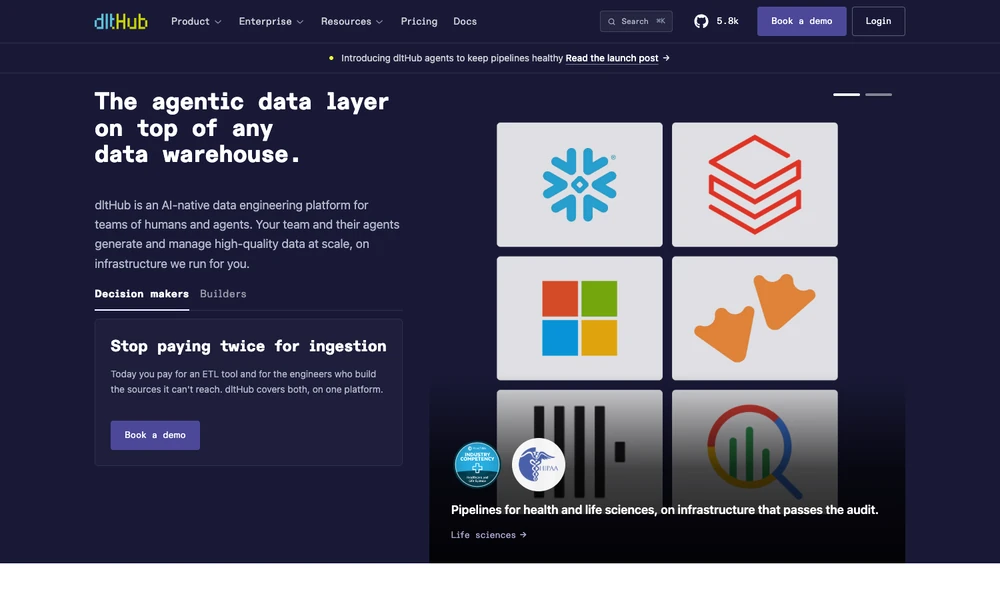
dltHub builds and runs data pipelines around the open-source dlt Python library. Engineers can ingest information from APIs, databases, and files, then load it into an existing warehouse. Coding agents can help create or repair the pipeline code, while managed infrastructure schedules and operates the resulting workflow.
Lineage, schemas, quality rules, and run state provide context for investigating a failure. Schema contracts and dataset checks validate incoming data, and operational views bring runs and logs together. Transformation tools connect ingestion with downstream analysis. Python remains in the team's repository, giving engineers a code-based route for developing, deploying, and maintaining the pipeline.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentMove data into a warehouse and manage ingestion with built-in transformations
Build and manage warehouse pipelines through visual tools and the Maia platform
Synchronize database changes, SaaS data, and streams through one pipeline
Centralize data with managed integration pipelines
Move data between sources and analytical systems
Manage data pipelines as code with reusable open-source connectors