BrowserAct
Build reusable web data extraction bots from natural-language requests
Collect structured web data through APIs and visual scrapers
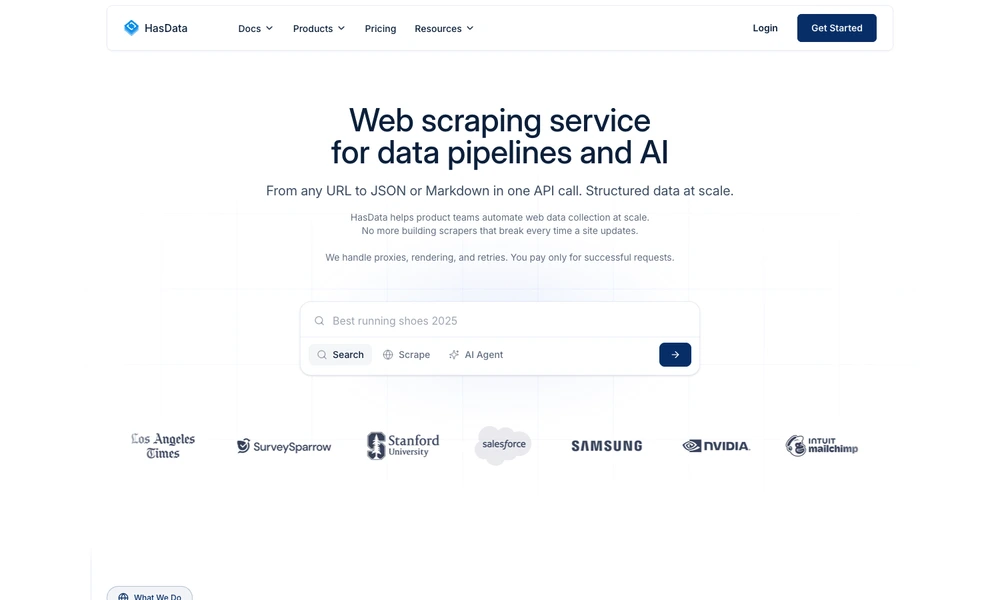
HasData collects web content for data pipelines, applications, and AI workflows. Developers send a URL to its API and receive structured JSON or Markdown, with browser rendering, proxy handling, and retries managed by the service. Dedicated endpoints cover sources such as search results, maps, news, flights, and product information, while AI extraction lets users describe the fields they need.
People who prefer a visual workflow can configure supported scrapers, schedule runs, and export results as CSV, spreadsheets, or JSON. The platform also offers prepared datasets and recurring custom collection. Integrations connect extracted data to automation and AI tools, making it useful for research, monitoring, and keeping application datasets current.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentBuild reusable web data extraction bots from natural-language requests
Extract structured website data through prompts, schemas, and a web scraping API.
Run web scraping and browser automation workflows
Retrieve structured web data through task-specific APIs for AI agents
Retrieve web pages and structured data through a scraping API
Collect web data through an API or a managed extraction service