Scorecard
Test AI agents against realistic scenarios and compare evaluation results
Compare AI models through benchmark results, pricing, speed, and context limits
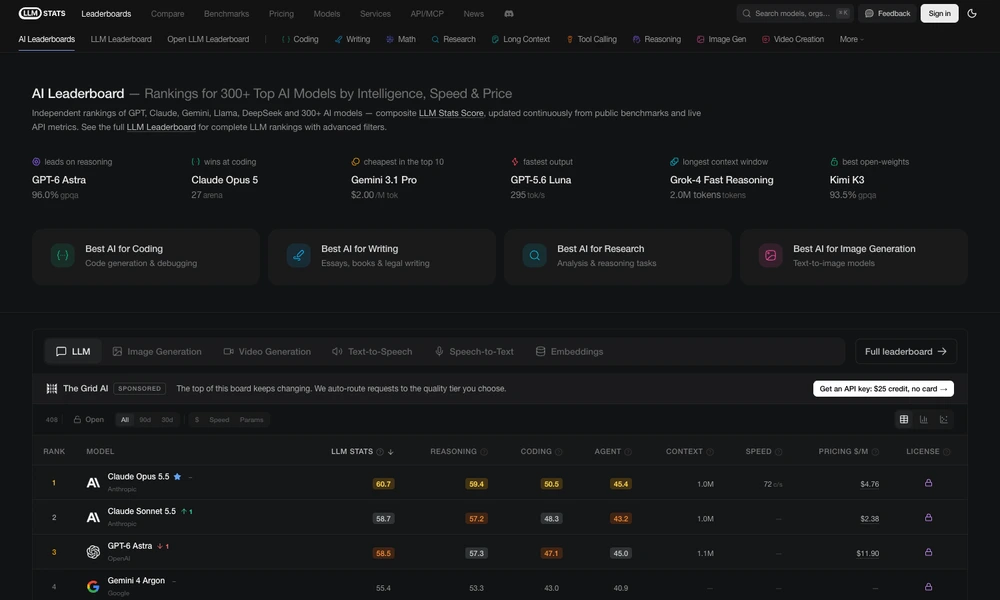
LLM Stats brings AI model benchmarks and practical deployment information into a searchable comparison site. Users can browse leaderboards for tasks such as coding, reasoning, writing, and research, then compare models by published scores, pricing, context windows, speed, and licensing. Separate sections cover image, video, speech, and embedding models.
The site combines public benchmark information with API measurements and explains how its composite ratings are calculated. Filters, model pages, and comparison views help developers narrow a shortlist before evaluating models for their own application. News, benchmark pages, and API or MCP access provide additional ways to follow model changes and use the collected information.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentTest AI agents against realistic scenarios and compare evaluation results
Turn agent conversation traces into tested improvement pull requests
Find recurring AI agent failures and investigate production traces
Evaluate voice AI conversations and identify where systems need improvement.
Compare computer-use agents through live tasks, recorded attempts, and human preferences.
Prepare data, configure model training, evaluate checkpoints, and ship through one CLI.