Scorecard
Test AI agents against realistic scenarios and compare evaluation results
Compare AI models on practical OpenClaw agent tasks
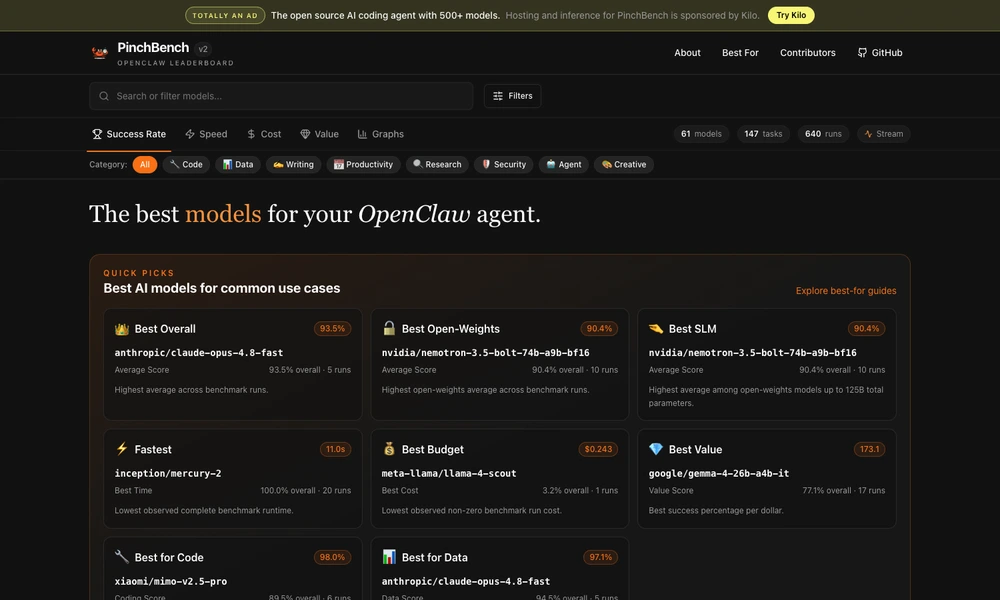
PinchBench is a public benchmark for comparing how AI models perform as OpenClaw agents. Its leaderboard measures task completion alongside speed, cost, and value, with filters for areas such as coding, data analysis, research, writing, and productivity. Users can inspect overall results or focus on categories relevant to their own agent workloads.
The site publishes both best and average scores and shows how many runs support a result. Tasks and grading criteria are open source, with evaluation using automated checks and an LLM judge. It offers a practical starting point for choosing models while making the benchmark's task definitions and measurement approach available for closer inspection.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentTest AI agents against realistic scenarios and compare evaluation results
Compare prompts across models and keep evaluation results in your browser workspace.
Find recurring AI agent failures and investigate production traces
Compare models and optimize prompts using application-specific evaluations
Trace agent runs and validate reusable fixes for failures
Build task-specific evaluators and guardrails for AI agents