Nebius
GPU cloud infrastructure for AI training and inference
Deploy dedicated inference capacity across GPUs and alternative accelerators
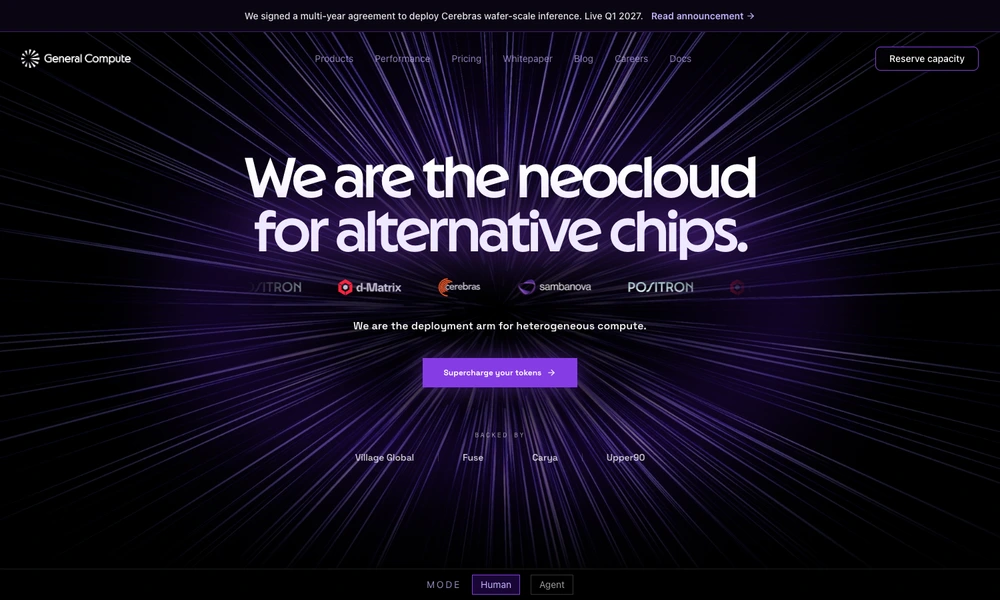
General Compute supplies dedicated computing capacity for AI inference across GPUs and specialized accelerators. Customers specify their models, traffic patterns, latency targets, and deployment requirements, then arrange capacity under a contract. The service covers hardware sourcing, colocation, power and cooling requirements, system bring-up, and ongoing operations.
Its approach separates parallel prompt processing from token generation where suitable, using different hardware for those stages. Customers can work with bare-metal systems or a managed endpoint, depending on the arrangement. The advertised hardware portfolio spans several accelerator vendors, but availability differs by system and deployment schedule; the announced Cerebras service is planned for early 2027. Pricing and capacity are quoted for the particular term, volume, and site.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentGPU cloud infrastructure for AI training and inference
Run local scripts on cloud CPUs or GPUs and bring their results back automatically.
Provision virtual machines from AI assistants and developer tools
Compare cloud architectures and generate reviewable infrastructure plans
Rent cloud servers, dedicated hardware and storage for websites and applications.
Persistent Linux machines for running AI-generated code and applications.