ZeroGPU
Run specialized AI workloads across edge and cloud infrastructure
An inference exchange where providers compete for each model request.
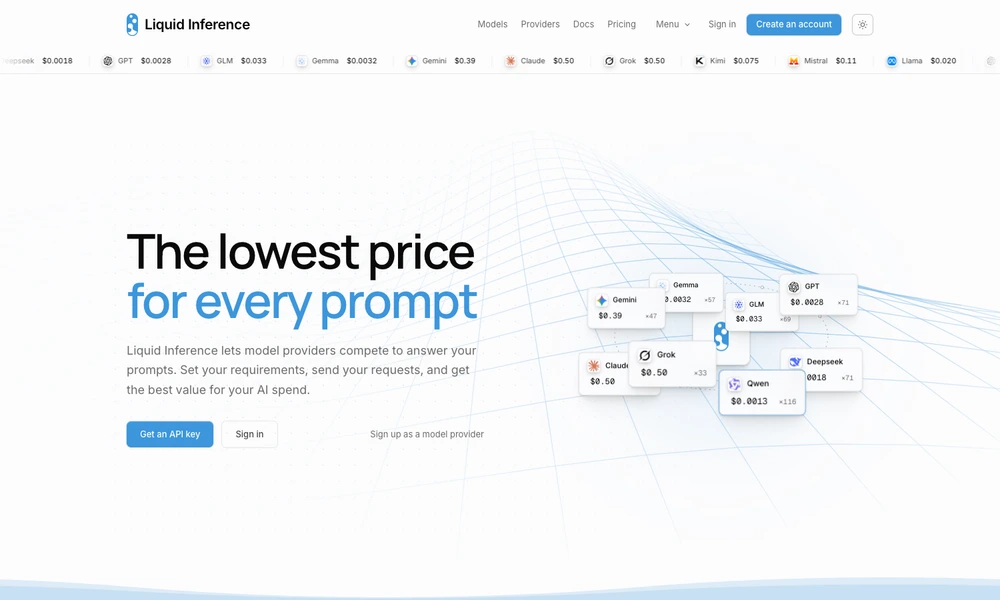
Liquid Inference routes model requests through an exchange where providers offer their inference capacity. Developers choose requirements such as model, region, speed, and minimum quality, then the service selects a qualifying offer for each request. Providers can adjust their token prices as available capacity changes, while buyers see itemized usage and published market data.
The exchange works with clients that support OpenAI or Anthropic API formats by changing the endpoint and credentials. A command-line tool also connects coding agents to the exchange with ranking and spending controls. It is useful for teams that want to compare inference options and manage routing across providers within an existing application.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentRun specialized AI workloads across edge and cloud infrastructure
Access and govern AI models through a unified gateway
Access language and media models through a unified API
Build AI applications on managed model infrastructure.
Access AI models through one API with spending and usage controls
Access multiple AI models through one gateway with usage and cost visibility