Liquid Inference
An inference exchange where providers compete for each model request.
Run specialized AI workloads across edge and cloud infrastructure
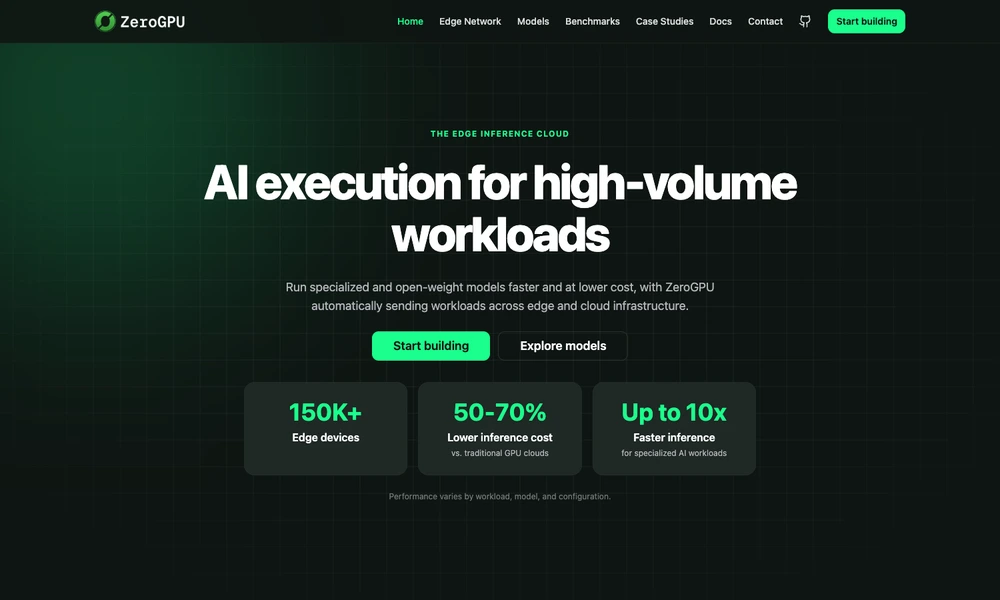
ZeroGPU is an inference service for high-volume, repeatable AI workloads. It offers specialized models alongside supported open-weight models, with tasks including content classification, moderation, information extraction, embeddings, reranking, speech, and document processing. Applications send requests to the service, which routes work across its edge and cloud infrastructure.
The platform provides serverless model access with monitoring and cloud fallback, so teams do not have to provision a dedicated machine for each workload. An OpenAI-compatible interface supports integration with existing application code, while model-specific pricing tracks usage. Developers can choose a small task-focused model when a general assistant is unnecessary. Actual latency, throughput, and cost depend on the model, input, and deployment configuration.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentAn inference exchange where providers compete for each model request.
Add a fast decision layer to an AI agent’s execution workflow.
Access and govern AI models through a unified gateway
Access language and media models through a unified API
Build AI applications on managed model infrastructure.
Access AI models through one API with spending and usage controls