Coarena
Compare computer-use agents through live tasks, recorded attempts, and human preferences.
Trace, evaluate, and optimize prompts and AI agent configurations
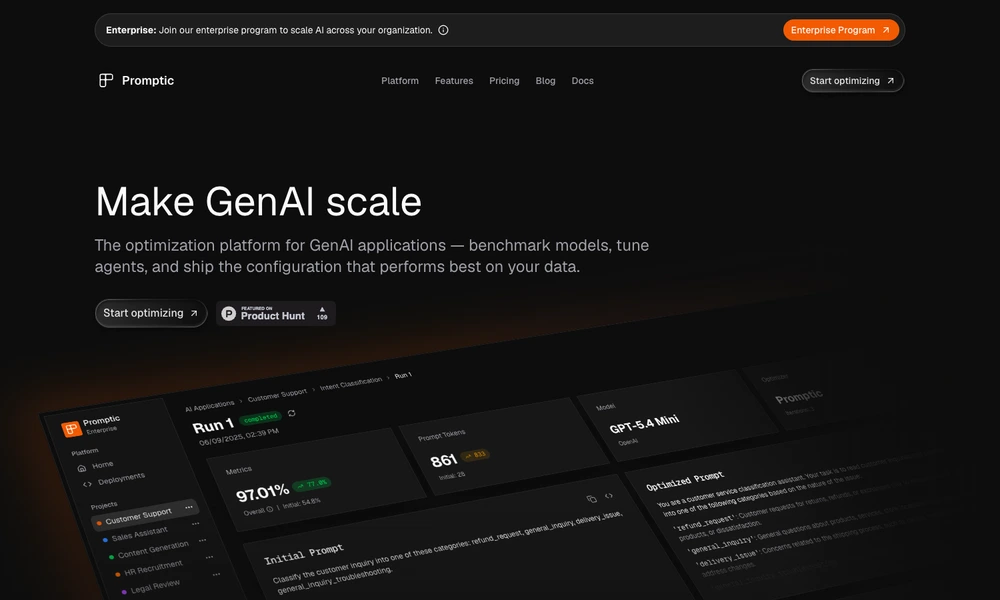
Promptic helps teams evaluate and improve applications built with language models. Users provide examples with expected outputs, choose metrics such as quality, cost, and latency, and compare candidate models or prompts on the same dataset. The platform can then optimize prompts and agent configurations against those chosen criteria.
OpenTelemetry-based tracing captures model calls, tool activity, tokens, and timing so developers can inspect where a workflow succeeds or breaks down. These traces can feed later experiments rather than remaining isolated logs. Promptic also provides tools for coding agents to investigate results and propose changes, supporting an iterative process in which new configurations are measured before teams decide what to ship.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentCompare computer-use agents through live tasks, recorded attempts, and human preferences.
Turn agent conversation traces into tested improvement pull requests
Compare prompts across models and keep evaluation results in your browser workspace.
Source training datasets and custom collections for robotics and physical AI
Explore a benchmark linking product launches with later funding
Simulate realistic users to test voice and chat agents