Ramp Router
Route model requests through one endpoint with fallbacks and usage visibility.
Access hosted inference for open-weight language models
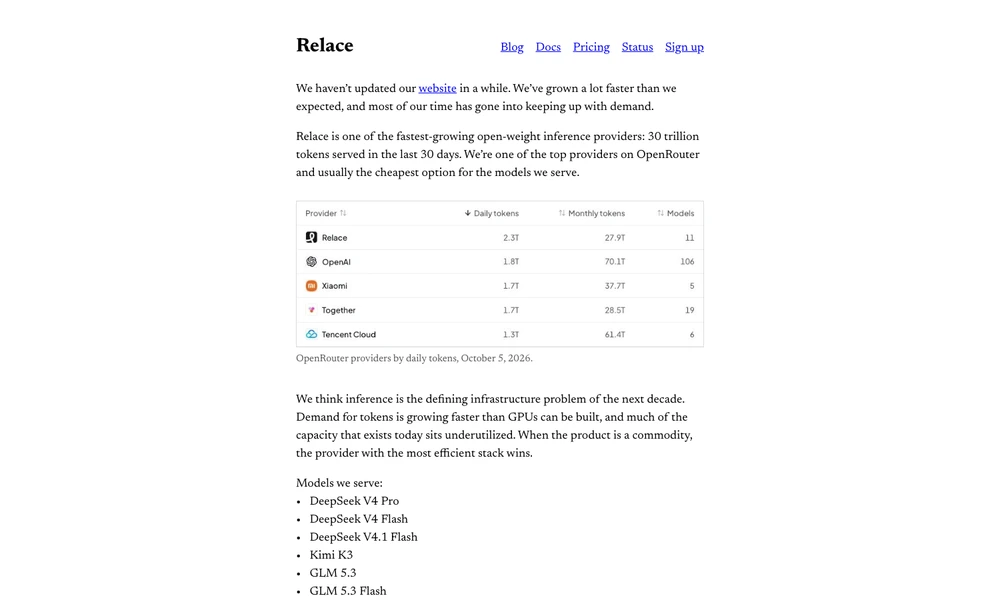
Relace provides hosted inference for open-weight language models. Developers can obtain an API key through its application or access supported models through OpenRouter, giving them a way to use model capabilities without operating their own GPU infrastructure. Its current model selection includes families from DeepSeek, Moonshot, and Z.ai.
The service focuses on running models efficiently at scale, with documentation, pricing information, and a service-status page available for integration planning. Teams can compare the available models against their workload and budget before choosing an endpoint. Relace is useful for applications that need managed access to open-weight models and substantial token-processing capacity.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentRoute model requests through one endpoint with fallbacks and usage visibility.
Add a fast decision layer to an AI agent’s execution workflow.
Model APIs, agent sandboxes, and GPU infrastructure for AI applications
Route and monitor model inference with provider and budget controls
Access language and media models through a unified API
Cloud inference for applications built on AI models