Cerebras
AI inference services built on wafer-scale computing
Cloud inference for applications built on AI models
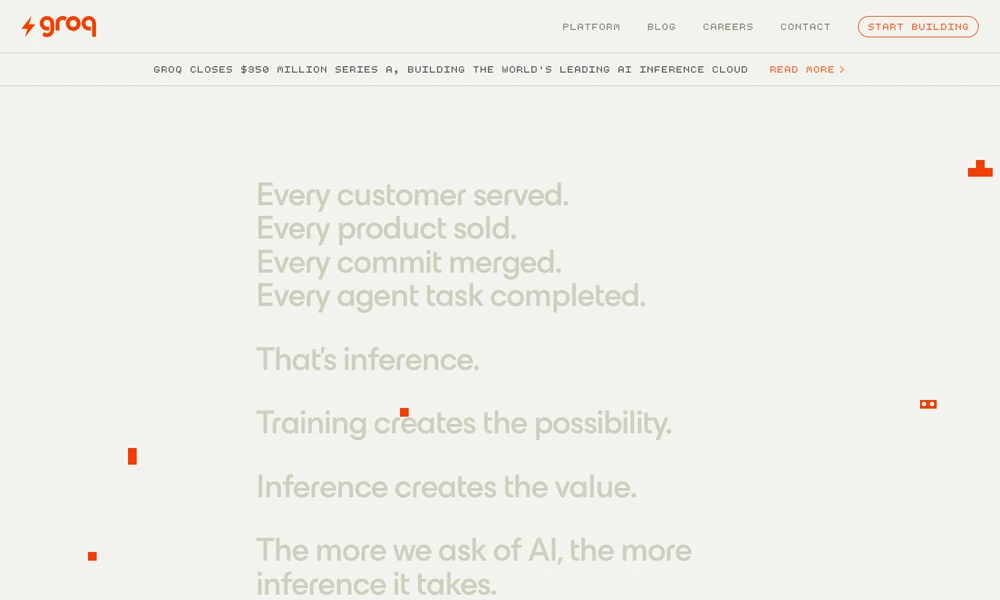
Groq serves AI models through cloud inference APIs and computing infrastructure. Inference processes a request with a trained model to produce a response, including text or supported audio output. Developers use its OpenAI-compatible interface or SDKs to connect those responses to their applications.
The platform includes model-dependent tools for structured output, speech processing, tool calls, and external integrations. Service tiers and batch processing provide options for different workloads, while projects and permissions organize access. Groq's infrastructure also supports larger deployments for organizations running repeated model requests, with the selected model and service defining the available capabilities.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentAI inference services built on wafer-scale computing
Route model requests through one endpoint with fallbacks and usage visibility.
Access hosted inference for open-weight language models
Add a fast decision layer to an AI agent’s execution workflow.
Model APIs, agent sandboxes, and GPU infrastructure for AI applications
Route and monitor model inference with provider and budget controls