Helicone
Route, inspect, and monitor requests across AI applications
Monitor model requests and review ways to reduce LLM operating costs.
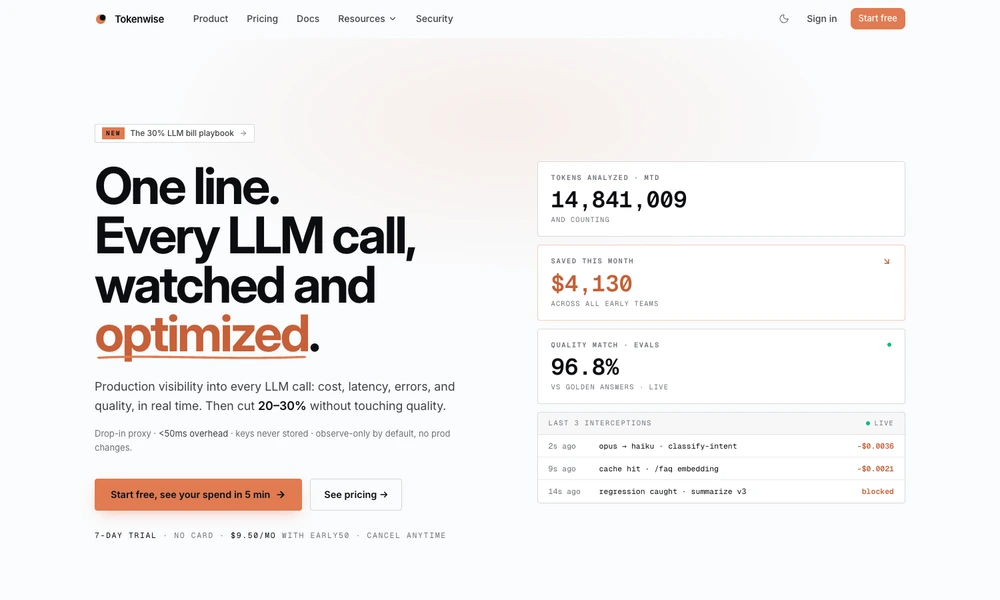
Tokenwise is an observability and cost-management service for applications that call large language models. Developers route requests through a compatible proxy to see costs, token use, latency, and errors by model, application, or tag. The initial observation mode collects visibility before the team chooses to change request behavior.
The platform identifies opportunities such as repeated requests, oversized prompts, and workloads that might use a less expensive model. Proposed changes can be replayed against a quality baseline before being applied. Alerts and budget controls help teams track unexpected changes, while workspaces and reporting support the ongoing operation of AI applications.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentRoute, inspect, and monitor requests across AI applications
Inspect coding-agent traces, token usage, and execution costs
Combine AI traces with logs, metrics, and application observability
Understand AI coding sessions, costs, and team workflows
Investigate production issues and propose fixes as pull requests
Application monitoring with connected telemetry and traces