SGLang
Serve large language and multimodal models on your own infrastructure
Run efficient language model inference with an OpenAI-compatible server
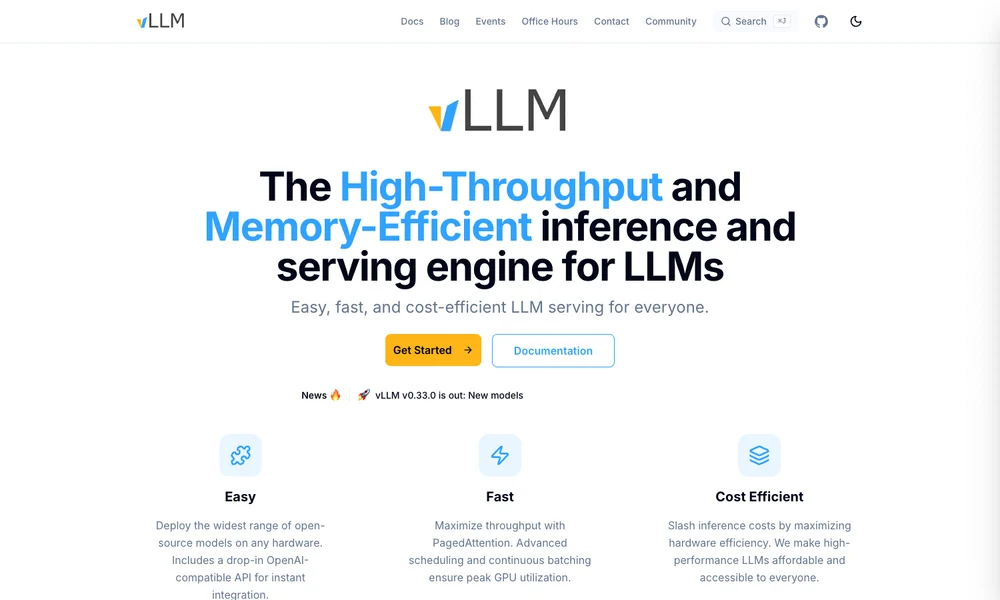
vLLM is an open-source inference and serving engine for large language models. It helps developers deploy supported models behind an OpenAI-compatible API, allowing existing applications to connect to infrastructure they operate themselves. Installation options include Python packages and Docker, with support for multiple accelerator and CPU platforms.
The engine uses PagedAttention to manage model memory and continuous batching to process incoming requests efficiently. Its scheduling focuses on keeping hardware busy while serving many users, making it useful for teams running chat applications and other services that generate text. Developers can start with the stable release and consult the documentation to choose compatible models, hardware, and deployment settings.
Tried it? Share a useful thought or ask a question.
Sign in to join the discussion.
Sign in to commentServe large language and multimodal models on your own infrastructure
Trace, evaluate and manage models, LLM applications and agents
Post-train and serve AI models across different accelerators
Compare models and optimize prompts using application-specific evaluations
Train specialized models for recurring production workflows
Compare AI models across creative, coding, and reasoning tasks