Groq
Cloud inference for applications built on AI models
AI inference services built on wafer-scale computing
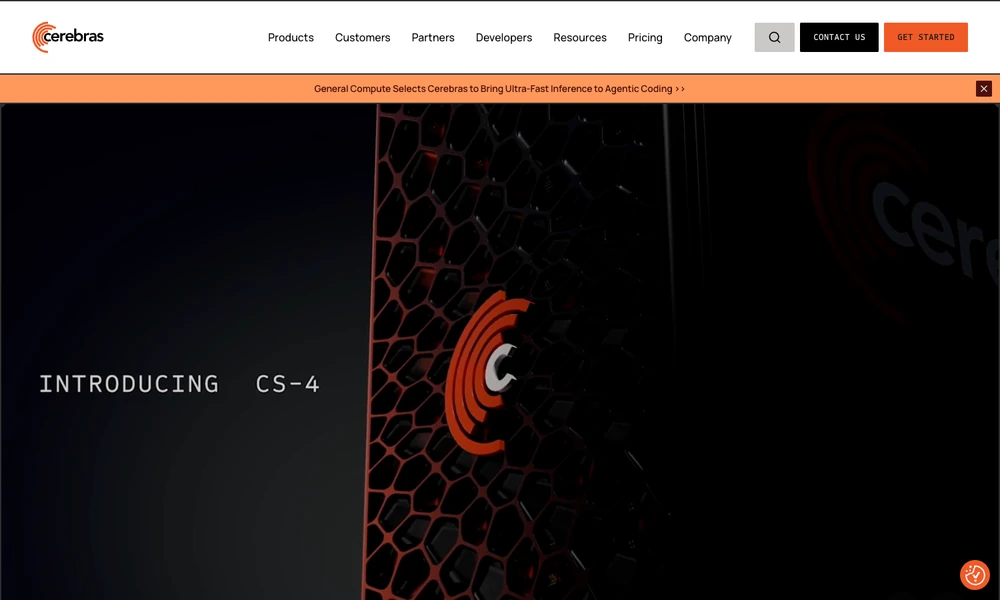
Cerebras provides AI computing systems and hosted inference for applications using supported models. Developers send requests through its API or SDKs, with OpenAI-compatible interfaces for adapting existing integrations. The service supports coding, reasoning, voice, and agent workloads.
Dedicated inference offers reserved capacity and private endpoints for organizations with particular deployment requirements. Cerebras also provides training and fine-tuning options around its wafer-scale infrastructure. Teams can use hosted model calls within an application or evaluate hardware and dedicated-service arrangements for a larger workload, with supported models and capacity defined by the service they choose.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentCloud inference for applications built on AI models
Route model requests through one endpoint with fallbacks and usage visibility.
Access hosted inference for open-weight language models
Add a fast decision layer to an AI agent’s execution workflow.
Model APIs, agent sandboxes, and GPU infrastructure for AI applications
Route and monitor model inference with provider and budget controls