Msty
A private AI workspace for models, reusable prompts, and personal knowledge
Serve local AI models on Apple silicon with persistent caching.
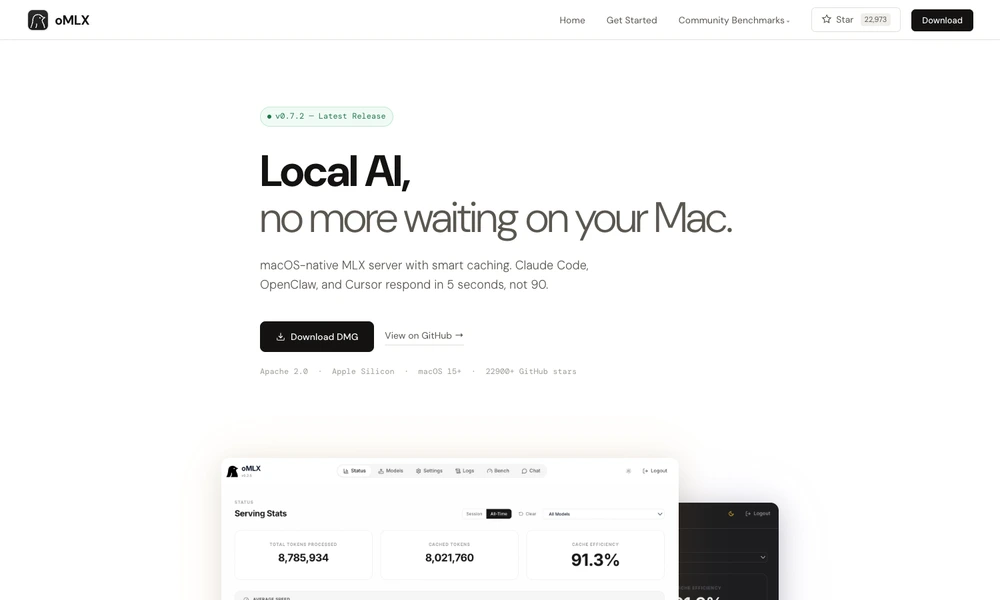
oMLX is an MLX-based inference server for Apple silicon Macs. It stores reusable model cache blocks on SSD as well as in memory, allowing previous prompt prefixes to be restored across requests and server restarts. Continuous batching supports concurrent work, and the server can manage language, vision-language, embedding, and reranking models.
A native menu-bar app controls the server, while a web dashboard provides model downloads, chat, and operating metrics. OpenAI-compatible and Anthropic-compatible endpoints let existing coding tools use the local backend. Users can point oMLX at supported model folders they already have. The project is open source and also includes configurable tool-calling and MCP integration.
Tried it? Share a useful thought or ask a question.
Good conversations start with a hello.
Sign in to commentA private AI workspace for models, reusable prompts, and personal knowledge
A self-hosted interface for local and cloud AI models
Run supported language models locally on Apple Silicon
Chat with local AI models and documents on your computer
Use local and cloud models in an open-source chat app.
Run open AI models on your own computer.